What Is AI Search Monitoring and What Should Brands Track?
AI search monitoring is the recurring measurement of how a brand appears across AI-generated answers for a controlled set of information needs and platforms. As the Microsoft Bing Blog explains, “We are happy to introduce AI Performance in Bing Webmaster Tools, a new set of insights that shows how publisher content appears across Microsoft Copilot, AI-generated summaries in Bing, and select partner integrations. For the first time, you can understand how often your content is cited in generative answers, with clear visibility into which URLs are referenced and how citation activity changes over time.”
The challenge is turning those observations into a measurement system without mistaking a sample for the whole market. At Content Ops Lab, that means connecting visibility monitoring to the same verification and performance architecture used to govern content production.
Related: What Does Google Search Console’s AI Search Report Actually Measure?
What Does AI Search Monitoring Actually Measure?
AI search monitoring measures recurring patterns of brand presence, source use, competitive visibility, answer context, and downstream performance across a defined measurement panel. It does not produce a census of every question users ask an AI platform. The useful output is a set of separate signals you can compare across platforms and over time.
Brand Visibility in Generated Answers
Brand visibility starts with whether the brand appears at all and how the answer presents it. That requires more context than a binary mention count provides.
- Brand named within a generated answer
- Brand recommended for a relevant need
- Brand included among competing alternatives
- Brand prominence within the answer context
Presence shows whether the brand appears in the answer, but it does not show which sources supported that presence.
Citation Visibility and Source Use
Citation monitoring asks a different question: which pages, domains, and third-party sources an AI system uses when constructing an answer containing relevant information.
- Brand-owned pages cited as sources
- Third-party pages reinforcing brand claims
- Competitor domains appearing in citations
- Source patterns changing across repeated measurements
A brand can be mentioned without being cited, making mention visibility and citation visibility separate measurement layers.
Business Impact Beyond Visibility
Visibility becomes commercially meaningful only when marketers connect it to measurable behavior after exposure. The chain can extend from AI referrals through conversion and revenue data.
- Identifiable AI referral sessions reaching pages
- Engagement quality from AI-originated visitors
- Leads and conversions from visible referrals
- Revenue tied to attributable AI sessions
Those outcomes belong in the monitoring system, but citation presence alone cannot prove that it caused them.
How Is AI Search Monitoring Different From Rank Tracking?
Traditional rank tracking measures a relatively fixed relationship between a keyword, a search engine, and an ordered result. AI-generated answers synthesize information from multiple sources and can mention one brand while citing another. Rankings may still influence retrieval, but they are no longer sufficient as the primary model for measuring AI visibility.
Rank Position Versus Answer Presence
A conventional ranking gives marketers a numbered position. Generated answers instead create a response in which several brands and sources can contribute without occupying a stable numerical slot.
- Search rankings return ordered result positions
- AI answers synthesize multiple retrieved sources
- Brands may appear without direct citations
- Sources may contribute without brand mentions
That difference changes the unit being monitored from a fixed position to participation within an answer system.
| Measurement Question | Traditional Rank Tracking | AI Search Monitoring |
| What is observed? | Keyword position | Answer presence and source participation |
| Primary unit | Keyword | Information need or prompt family |
| Competitive context | SERP positions | Mentions, citations, share of voice |
| Source behavior | Ranking URL | Multiple cited or retrieved sources |
| Stability | Relatively repeatable positions | Variable generated responses |
| Business layer | Organic traffic and conversion | AI referrals, engagement, leads, revenue |
Mentions Versus Citations
Mentions and citations describe different forms of visibility and should not be treated as interchangeable. A system may discuss a brand without linking to the brand’s own content.
- Mentions show brand presence in responses
- Citations identify sources used by answers
- Mentioned brands may lack cited pages
- Cited sources may support broader claims
Ahrefs defines the distinction directly: “Here’s what the key metrics mean: – Mentions — show how many AI responses include your brand – Citations — show how many AI responses cite your brand – Impressions — show the potential exposure by weighing mentions against Google’s search volume – AI Share of Voice — shows the % of brand impressions you own when compared to competitors.”
Why Share of Voice Requires Competitive Context
Share of voice adds the competitive layer by asking how frequently a brand appears relative to a defined competitor set. The result depends on the measurement panel.
- Competitor selection changes the comparison baseline
- Prompt coverage affects observed visibility share
- Platform selection changes competitive exposure
- Weighting methods influence composite results
Share of voice is useful for relative movement, but it should not be presented as an absolute measure of market visibility.
What Should Brands Monitor Instead of Individual Prompts?
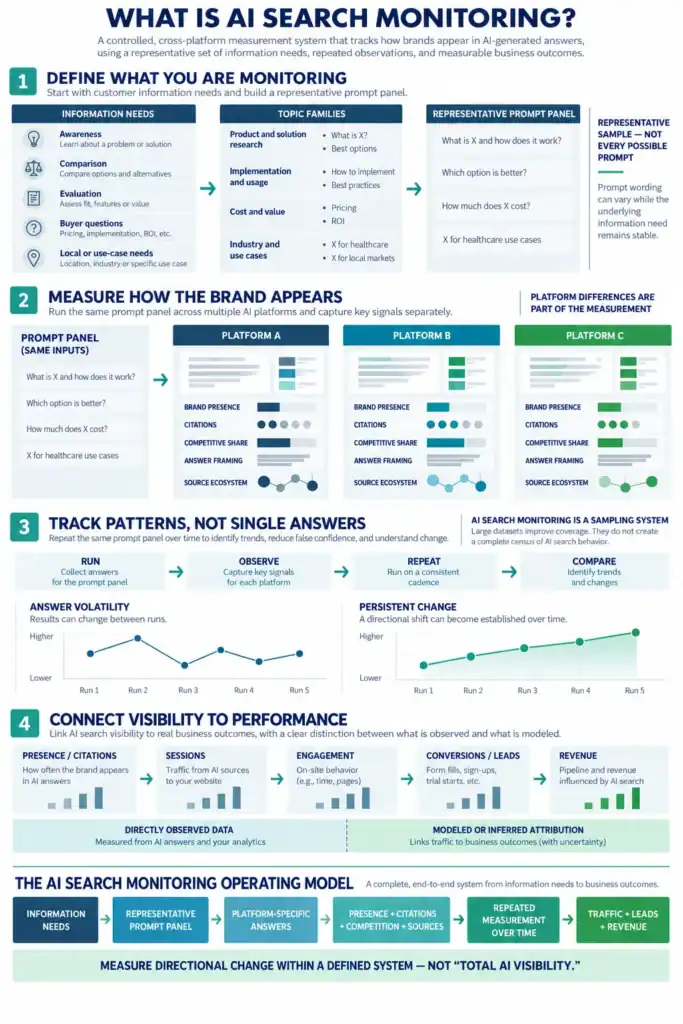
Brands should monitor stable information needs and topic families rather than treating individual prompt wording as durable demand. Prompts become observations within a broader measurement panel organized around topics, audiences, funnel stages, use cases, comparisons, and buyer questions. This creates enough consistency for longitudinal measurement without pretending the prompt universe is fixed.
Information Needs and Topic Families
An information need is more stable than the exact sentence a user types. Multiple prompts can express the same underlying question while using substantially different wording.
- Topics capture broader areas of demand
- Personas change context around similar needs
- Funnel stages alter the required answer
- Use cases create different decision criteria
As Semrush explains, “Unlike keywords, individual prompts are often too specific and unique to measure directly. That’s why Semrush calculates topic-level volume in our Prompt Research report. Each topic groups together related prompts that move in the same ‘semantic direction,’ giving you a meaningful estimate of demand.”
Representative Prompt Panels
A prompt panel turns those information needs into a controlled sample that can be run repeatedly. Its purpose is representation, not exhaustive coverage of every possible query.
- Cover priority topics and buyer questions
- Include meaningful persona and intent variations
- Represent informational and commercial demand
- Preserve enough consistency for trend analysis
For example, one topic family around AI search measurement might include:
Topic family: Measuring AI search performance
- How do brands measure AI visibility?
- What should an AI search report include?
- How do AI citations affect reporting?
- Which AI visibility metrics matter most?
- How should executives report AI search?
Scrunch describes the sampling approach this way: “The brands winning AI search are building stable prompt libraries organized by topic, persona, and funnel stage to measure what changes over time. … Use this heuristic as your starting point: X [# of topic clusters] × Y [12-15 questions per cluster] = Z [# of prompts to track]. The goal is a representative sampling of data you can track consistently over time using a tool like Scrunch.”
Stable Panels Versus Continuous Refinement
A useful monitoring panel cannot change every reporting cycle. Constantly replacing prompts destroys the baseline marketers need to distinguish actual movement from measurement changes.
- Maintain a stable core prompt set
- Document additions and removals explicitly
- Add emerging demand in controlled batches
- Preserve historical comparability where possible
The panel should evolve as demand changes, but the measurement design must make those changes visible rather than silently rewriting history.
If your operation needs to produce 20–50+ articles per month without sacrificing compliance or quality, Content Ops Lab builds the infrastructure to make that possible. Contact us to discuss your content production requirements.
Which AI Search Metrics Should Brands Track?
Brands should track AI search metrics in separate measurement layers: demand coverage, presence, citations, competitive visibility, framing, source behavior, and business outcomes. Combining them too early creates a cleaner dashboard but a weaker analysis. Marketing leaders need to know which part of the system changed before deciding what action to take.
Presence, Citations, and Competitive Visibility
The first measurement layer establishes whether the brand appears, whether its content is used, and how its visibility compares with selected competitors.
- Brand presence across monitored answer sets
- Citation frequency for owned content
- Competitive share across prompt families
- Coverage across priority information needs
These metrics describe visibility within the monitored sample, not the total universe of AI-assisted research and decision-making.
Brand Framing and Source Ecosystems
Monitoring should also capture how the brand is described and which external sources shape that description. This exposes reputation and corroboration patterns that counts alone miss.
- Recommendation context surrounding brand mentions
- Attributes repeatedly associated with brands
- Third-party sources influencing answer construction
- Source concentration around specific domains
Framing or sentiment should not be treated as factual accuracy; a positive answer can still contain incomplete or incorrect information.
Referral Traffic, Leads, and Revenue
The final layer asks whether measurable AI-originated visits contribute to business performance. These outcomes should remain separate from visibility and citation metrics.
- Visible referral sessions by AI source
- Landing pages receiving AI traffic
- Conversion and lead quality trends
- Revenue from directly attributable sessions
A practical measurement architecture keeps each signal distinct:
| Measurement Layer | What It Indicates | What It Cannot Establish Alone |
| Demand coverage | Information needs represented | Total AI demand |
| Brand presence | Frequency of brand appearance | Source influence |
| Citation visibility | Brand content used as evidence | Business impact |
| Competitive visibility | Relative presence within sample | Total market share |
| Brand framing | How answers describe the brand | Factual accuracy |
| Source ecosystem | Domains shaping responses | Why a source was selected |
| Business outcomes | Observable commercial performance | Full attribution |
Keeping those layers separate makes diagnosis possible when one signal improves while another remains flat.
Related: What Causes AI Visibility Volatility?
Why Should AI Search Monitoring Stay Separate by Platform and Over Time?
AI search monitoring should preserve platform-level differences and measure repeated observations over time. The same underlying information need can produce different brands, citations, sources, and answer framing across systems. Repetition doesn’t remove generative variation; it creates enough observations to distinguish isolated outputs from persistent patterns.
Cross-Platform Variance
Different answer systems can retrieve different sources or construct different responses from similar information needs. Blending every platform into one score hides those distinctions.
- Track each platform as separate layer
- Compare equivalent information needs across systems
- Preserve platform-specific citation patterns
- Report blended summaries only with components
An executive scorecard can summarize performance, but operators still need the platform-level data required to explain why it changed.
Prompt Sensitivity and Answer Volatility
Even small wording changes can alter generated outputs. That makes any single prompt run a weak basis for declaring a brand visible or invisible.
- Minor wording changes can alter answers
- Citation sets may shift between runs
- Recommendation context can change unexpectedly
- Single observations create false confidence
Research published in the ACL Anthology found: “We find that even the smallest of perturbations, such as adding a space at the end of a prompt, can cause the LLM to change its answer.”
Repeated Measurement and Rolling Trends
Repeated observation turns volatility into a measurable property rather than a reason to abandon monitoring. The objective is not perfect repeatability but more interpretable directional change.
- Run stable panels on consistent schedules
- Compare rolling periods instead of snapshots
- Track persistent gains and losses
- Investigate abnormal platform-level movement separately
Daily measurement does not eliminate variability; it simply produces additional observations from which more durable trends can emerge.
Why Is AI Search Monitoring Fundamentally a Sampling Problem?
AI search monitoring is fundamentally a sampling problem because no current measurement system observes every prompt, answer, retrieval event, or citation generated across the market. Commercial tools and first-party reports both work from finite datasets. Their value comes from controlled, representative observation—not from providing an exact census of AI search behavior.
No Tool Sees the Complete Prompt Universe
Very large datasets improve coverage, but size and completeness are not the same thing. A monitoring system still observes a defined universe selected by its methodology.
- Commercial datasets cover finite prompt sets
- User behavior extends beyond tracked prompts
- Coverage varies by platform and language
- Sampling methods shape reported visibility
The Ahrefs Help Center describes Brand Radar this way: “Brand Radar is Ahrefs’ AI visibility tool that tracks how any brand shows up in AI search in over 405+ million search-backed prompts … Brand Radar allows you to check AI responses for 405+ million search-backed prompts across 7 AI platforms.”
That is substantial coverage, but even a large sample does not make the dataset exhaustive.
First-Party Reporting Is Also Partial
First-party access does not automatically mean complete observation. Platform reports can expose data unavailable to third-party tools while still presenting sampled information.
- First-party reports provide platform-native evidence
- Available fields depend on platform design
- Reported samples may exclude activity
- Coverage definitions can change over time
The Microsoft Bing Blog makes the limitation explicit: “Grounding queries — Shows the key phrases the AI used when retrieving content that was referenced in AI-generated answers. The data shown represents a sample of overall citation activity.”
Why Composite Scores Can Create False Precision
Composite visibility scores can be useful for executive trend reporting, but they compress several methodological choices into one number. That number inherits every limitation in the underlying sample.
- Prompt selection affects observed performance
- Competitor sets alter relative scoring
- Platform weights influence blended results
- Scoring formulas impose analytical assumptions
The right interpretation is directional: a score summarizes movement under a defined methodology, not a precise percentage of total AI visibility.
How Should Marketing Leaders Connect AI Visibility to Business Outcomes?
Marketing leaders should connect AI visibility to business outcomes through a measurement chain rather than assuming visibility equals value. Track observable citations and presence first, then identifiable sessions, engagement, conversions, leads, and revenue. Modeled attribution can supplement that view, but it should remain visibly separate from directly observed referral data.
Visible AI Referral Traffic
Referral analytics provide the clearest downstream evidence when an AI platform passes identifiable source information. Isolate that traffic and evaluate it like a distinct acquisition channel.
- Segment identifiable AI referral sources
- Track landing pages receiving sessions
- Compare engagement with other channels
- Measure conversion behavior independently
Visible referral traffic cannot capture every AI-influenced visit, but it provides the cleanest directly observed bridge between visibility and site behavior.
Dark or Misattributed AI Traffic
Some AI-originated sessions can arrive without usable referral information and appear as direct or otherwise misclassified traffic. Estimates of this activity require caution.
- Keep observed referrals as baseline
- Model unattributed traffic separately
- Document attribution assumptions clearly
- Avoid converting estimates into facts
Nowoka Analytics reports: “What you can see is an undercount. Roughly 70% of AI visits arrive with no referrer and fall into Direct, so treat GA4 as the floor, not the ceiling.”
The 70% figure is a vendor-reported estimate, not a universal benchmark.
Executive Reporting From Visibility to Revenue
Executive reporting works best when it shows the measurement chain instead of replacing it with one synthetic KPI. Each stage answers a different business question.
Visibility / citations → sessions → engagement → conversions / leads → revenue
- Visibility measures answer-level participation
- Sessions measure observable site arrival
- Engagement measures post-click behavior quality
- Conversions connect traffic with business actions
- Revenue establishes directly attributable commercial value
The gaps between those stages matter as much as the totals because they show where evidence ends and interpretation begins.
How Does Content Ops Lab Approach AI Search Measurement?
Content Ops Lab treats AI search monitoring as one layer of a broader production and measurement system. In a 23-month regulated healthcare deployment, the operating model supported growth from roughly 10 to 50+ articles per month and more than 1,000 citation-verified articles and pages. Measurement is tied to what the content system produces, how claims are verified, where visibility appears, and what happens after an attributable visit.
For one 12-location regulated healthcare client, observed AI referral performance reached 21.4% average AI search CVR vs. 3.32% site average = 6.4x performance multiplier. That result describes the referral channel’s observed conversion performance; it does not establish that citation visibility caused those conversions.
The broader operating record includes:
- 23 months of live regulated-healthcare production
- More than 1,000 citation-verified articles and pages
- Output scaled from roughly 10 to 50+ monthly
- Research separated from downstream writing execution
- Citation verification built into production governance
- Multi-platform visibility measured beyond conventional rankings
- AI referral performance tracked alongside site outcomes
The point is not to manufacture one definitive AI score. It is to keep research, production, verification, visibility, and commercial measurement connected without collapsing distinct signals.
The Content Ops Lab Production System
The production system establishes controlled inputs and verification before interpreting performance signals, reducing the risk that reporting becomes detached from how content was actually produced.
- Research: Define demand, evidence, sources, and measurement context
- Verification: Check claims, citations, evidence fidelity, and boundaries
- Optimization: Structure content for search and AI retrieval
- Delivery: Publish, measure performance, and feed findings forward
That structure makes monitoring part of the operating loop, not a dashboard checked after publication.
Ready to build content infrastructure that scales without the compliance risk? Get in touch — we’ll assess your current content operation and outline what a systematic approach would look like for your organization.
FAQs About AI Search Monitoring
Can AI Search Monitoring Ever Be Accurate if AI Answers Keep Changing?
Yes, if accuracy means measuring recurring patterns rather than expecting identical answers. Stable prompt panels, repeated runs, platform-level reporting, and rolling comparisons can show directional movement despite generative variation. The goal isn’t to freeze AI answers into deterministic rankings. It is to build enough controlled observations to identify persistent changes in visibility, citations, competition, and source use.
How Many Prompts Should a Brand Track for AI Search Monitoring?
There is no universal prompt count. The panel should be large enough to represent priority topics, personas, funnel stages, comparisons, and buyer questions while remaining stable enough for repeated measurement. A smaller, deliberately constructed panel can be more useful than a larger collection of unrelated prompts if it better represents the information needs the business actually cares about.
What Are the Biggest Measurement Limitations in AI Search Monitoring?
The main limitations are sampling, prompt sensitivity, platform variance, incomplete first-party reporting, changing retrieval systems, and imperfect referral attribution. No current system observes the full prompt universe. Composite metrics also depend on methodological choices such as prompt selection, competitor sets, platform coverage, and weighting. Those limitations should shape interpretation rather than invalidate monitoring altogether.
Is AI Share of Voice More Useful Than Traditional Search Rankings?
They answer different questions. Rankings show where URLs appear for defined search queries, while AI share of voice measures relative brand visibility within a monitored AI-answer sample. Marketing teams may need both because search rankings can influence retrieval while AI visibility reveals whether brands actually appear in generated answers. Neither metric should be treated as complete on its own.
What Should an AI Search Monitoring Program Include Beyond Visibility Software?
A complete program needs a representative prompt framework, platform-level measurement, citation analysis, competitive monitoring, source analysis, answer-context review, referral analytics, conversion tracking, and documented reporting rules. It also needs governance around panel changes and attribution assumptions. Software supplies observations; the measurement architecture determines whether leadership can interpret those observations consistently and connect them to business outcomes.
Key Takeaways
- AI search monitoring measures recurring patterns across a controlled sample, not the complete universe of prompts and generated answers.
- Mentions, citations, competitive visibility, answer framing, source behavior, and business outcomes should remain separate measurement layers.
- Stable prompt families make longitudinal comparisons more defensible than chasing isolated questions or continually rebuilding the monitoring panel.
- Platform-level reporting should remain visible because blended scores can hide meaningful differences in citations, competitors, and source selection.
- Content Ops Lab connects monitoring with research, verification, optimization, delivery, and downstream performance rather than treating visibility as an isolated KPI.
- One regulated healthcare deployment recorded 21.4% AI search CVR versus 3.32% site average, reinforcing the need to measure beyond visibility.
- Build the baseline now, document its methodology, and measure directional change before emerging AI reporting conventions harden around weaker assumptions.
How Should Brands Build an AI Search Monitoring System That Holds Up Over Time?
AI search monitoring works best as a controlled measurement system, not a new version of keyword rank tracking. Brands need representative information needs, stable prompt panels, platform-specific observations, separate visibility and citation metrics, and a clear path from answer presence to measurable business outcomes. Sampling limits don’t make the data useless; they define how confidently you should interpret it.
The next step is to establish a documented baseline and preserve it long enough to measure change without confusing methodological changes for market movement. Content Ops Lab applies that same principle across research, verification, optimization, delivery, and performance measurement: keep the layers connected, keep their boundaries visible, and use repeated evidence to guide the next decision.
Related: How Do You Measure Success in AI Search Beyond Rankings and Traffic?
3 Comments
Comments are closed.